

Bioinformatics Market Top Key Players, Growth and Market Reports 2025

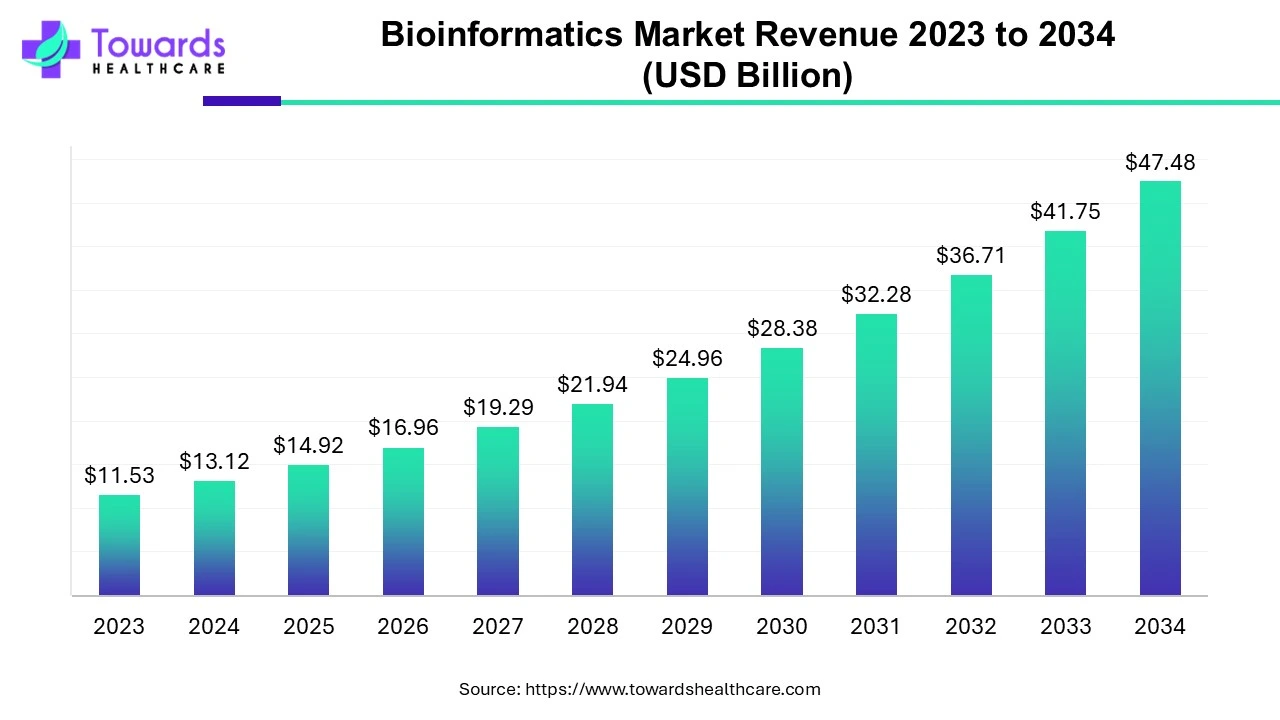
Market Size
Base & outlook (constant USD):
➣2023: US$ 11.53B (given)
➣2024 (implied base for CAGR): US$ 13.11B
➣2034: US$ 47.48B (given)
Select year projections (at 13.73% CAGR from 2024):
➣2025: US$ 14.92B
➣2027: US$ 19.29B
➣2029: US$ 24.95B
➣2031: US$ 32.28B
➣2033: US$ 41.75B
By product family (qualitative size dynamics):
➣Biocontent management (dominated 2023): growing on the back of unified platforms for generating/storing/delivering complex biological data.
➣Bioinformatics services (fastest growth): end-to-end data lifecycle management (intake → integrity → use), saving scientist time via expert bioinformaticians.
➣Bioinformatics platforms (steady expansion): sequence analysis/alignment/manipulation and structural/functional suites underpin day-to-day workflows.
➣Customer spending motions: increasing multiyear service contracts, managed analysis pipelines, and cloud data-ops alongside on-prem high-compute nodes where needed.
➣Deal sizes: moving from department-level tool buys to enterprise-wide frameworks attached to omics programs and translational medicine initiatives.
Market Trends
➣Genomic surveillance mainstreaming: WHO (Sept 2024) workshop advanced genomic surveillance/data-sharing/bioinformatics for respiratory viruses within GISRS, strengthening national–global readiness.
➣Services deepening: Almaden Genomics (Sept 2024) launched Data Management & Informatics Services to tackle data scale and complexity for pharma/biotech/academia.
➣Sequencing economics shifting: Inocras (Aug 2024) offering WGS on Ultima Genomics UG 100 highlights a push toward lower-cost, high-throughput WGS with custom bioinformatics stacks.
➣Large-scale clinico-genomic integration: Genomics England (Jan 2024) built a pipeline integrating 13,880 tumor WGS with matched clinical data to resolve germline & somatic drivers influencing prognosis.
➣CRISPR accuracy via AI: Würzburg Helmholtz Institute (Jan 2024) improved CRISPR efficacy prediction using ML-based data integration.
➣AI/ML pervasiveness: NLP literature mining, neural nets for structure prediction, and ML-assisted variant calling are accelerating insight cycles.
➣Omics expansion: Favorable government support for genomics, proteomics, metabolomics, transcriptomics keeps widening downstream informatics demand.
➣Enterprise data governance: Rising emphasis on quality, lineage, and FAIR data across pipelines to enable regulated clinical use.
➣Cloud-first workflows: Scale-out compute + elastic storage for cohort-scale analyses; hybrid architectures for sensitive datasets.
➣From ‘sick care’ to ‘health care’: Industry leaders (e.g., Li Qing’s remarks) emphasize genomics moving upstream into prevention & population health.
10 Deep AI Impacts / Roles in Bioinformatics
➣Variant discovery & prioritization: ML-enhanced variant calling, pathogenicity scoring, and phenotype-genotype linking for faster diagnostics.
➣Protein structure & function inference: Deep models accelerate structure prediction, binding-site mapping, and protein-protein interaction insights for target validation.
➣Drug discovery acceleration: AI for virtual screening, de-novo design, ADMET prediction, and multi-parameter optimization, cutting cycle times.
➣CRISPR guide optimization: ML models predict on-target efficiency and off-target risk to design safer, more effective edits.
➣NLP literature intelligence: Automated extraction of entities/relations from millions of papers—hypothesis generation and evidence aggregation at scale.
➣Multi-omics fusion: Graph and representation learning integrate genomics–transcriptomics–proteomics–metabolomics to reveal disease mechanisms.
➣Clinical decision support: AI-assisted molecular tumor boards: actionable variants, trial matching, and therapy ranking with transparent evidence trails.
➣Population genomics & surveillance: Streaming analytics for outbreak detection, lineage tracking, and antimicrobial resistance patterning.
➣Data ops & automation: Active learning and AutoML to tune pipelines, reduce manual QC, and maintain performance as data drifts.
➣Privacy-preserving analytics: Federated learning and privacy tech to analyze distributed cohorts without centralizing PHI.
Regional Insights
North America — 2023 leader
➣Policy & funding backbone: Support from NIST, NCTR, NCIP and others sustains standards, reference datasets, and oncology informatics programs.
➣Clinical adoption: Mature payer/provider ecosystems support WGS/NGS in oncology and rare disease, driving demand for validated pipelines.
➣Talent & infrastructure: Dense clusters of bioinformaticians, cloud hyperscalers, and specialized HPC centers.
➣Canada momentum: Oct 2023: US$ 15M toward a Pan-Canadian Genome Library to unlock genomic medicine value chains.
Asia–Pacific — fastest growth ahead
➣China: World’s #2 biopharma market; rapid advances in gene therapy/genome editing spur local sequencing and informatics capacity.
➣India & Japan: Attractive for investment due to demographics, R&D incentives, and infrastructure scale-up.
➣Japan (2022): “Strengthening Drug Discovery Venture Ecosystem Project” (~¥300B) catalyzes startups and platform tooling.
➣Healthcare expansion: Public and private initiatives upgrading data standards, biobanks, and training in clinical bioinformatics.
Europe
➣Public-private consortia: Pan-European programs harmonize standards (e.g., cancer & rare disease genomics) and boost cross-border data utility.
➣Regulatory rigor: Strong data-protection frameworks stimulate growth in privacy-preserving bioinformatics and audit-ready pipelines.
Latin America / Middle East & Africa
➣Early-stage but rising: Focus on capacity building, regional reference labs, and cloud-hosted platforms to bypass capex barriers.
➣Adoption gating factors: Budget constraints and skilled-talent shortages—offset via collaborations and managed services.
Market Dynamics
Drivers:
➣Surge in genomic/proteomic research and novel drug discovery;
➣Technological advancements in sequencing and analytics;
➣Supportive policies for omics (genomics, proteomics, metabolomics, transcriptomics).
Restraints:
➣Computational complexity of large-scale datasets;
➣High infrastructure costs (HPC, storage) limiting LMIC uptake.
Challenges:
➣Shortage of trained bioinformaticians;
➣Interoperability & data quality issues across disparate sources.
Opportunities:
➣Expansion of bioinformatics services (fastest-growing product segment);
➣Increasing genomic surveillance (e.g., WHO/GISRS), national genome libraries, and hospital molecular programs;
➣Cloud-first deployments, ML-native pipelines, and privacy-preserving analytics.

Get a Sample of this Report
Bioinformatics Market
